The uncensored LLM leaderboard results in one place: UGI and SpeechMap top models as of Nov 2026, what each measures, and why they disagree about Gemini.
The UGI leaderboard on Hugging Face is the main uncensored LLM leaderboard. As of its October 2026 data, Grok 4.20 tops the overall UGI score and community Heretic builds of Gemma 4 and Qwen 3.5 reach the maximum 10/10 willingness. SpeechMap.AI, which tests contentious political speech instead, ranks Google DeepMind first. The two boards measure different things and often disagree.
- 1,329 (data Oct 17, 2026)
- 415 releases, 2,120 prompts
- Grok 4.20 multi-agent, 70.0
- Google DeepMind, 86.8
Key takeaways
- UGI tops out at 70.0 for xAI's Grok 4.20 multi-agent beta; a community de-restricted GLM-4.6 is second at 69.8.
- Of 1,329 UGI entries, 66 score 9.5 or higher on willingness, and none of them is an official lab release. The best official score is 8.2.
- SpeechMap's October 14, 2026 lab table puts Google DeepMind first (86.8), then xAI (81.7) and Anthropic (71.9).
- Gemini 4 Argon answers 87.0% of SpeechMap's prompts yet scores 1.2 to 1.8 out of 10 on UGI willingness. Each board answers a different question.
- All numbers here are the leaderboards' own. Refusal Rate has not run its own tests yet.
Which LLMs are least censored right now?
On the UGI leaderboard, the most-used uncensored LLM leaderboard, the least censored models are community de-restricted open-weight builds, with xAI’s Grok as the least censored official model. UGI’s data was last updated October 17, 2026; we read it on November 10. The scores below are UGI’s, not ours.
UGI publishes three headline numbers. UGI combines knowledge of sensitive topics with willingness to answer. W/10 is willingness alone: “how far a model can be pushed before it refuses to answer or deviates from instructions”, from 0 to 10. NatInt is general knowledge and reasoning, which matters because a model that never refuses but knows little is not much use.
| UGI rank | Model | Type | UGI | W/10 | NatInt | Tested |
|---|---|---|---|---|---|---|
| 1 | Grok 4.20 multi-agent beta (4 agents) | Official, xAI | 70.00 | 6.5 | 56.34 | Mar 13, 2026 |
| 2 | GLM-4.6-Derestricted-v3 (ArliAI, thinking prefill) | Community de-restricted | 69.82 | 8.8 | 30.93 | Mar 2, 2026 |
| 3 | Grok 4 (0709) | Official, xAI | 67.83 | 6.0 | 65.17 | Sep 24, 2025 |
| 6 | gemma-4-31B-it-heretic (coder3101, thought prefill) | Community Heretic | 65.69 | 10.0 | 36.53 | Apr 12, 2026 |
| 7 | DeepSeek-V3.2-Speciale | Official, DeepSeek | 65.37 | 4.8 | 53.02 | Dec 3, 2025 |
| 9 | Grok 4.20 (0309, reasoning) | Official, xAI | 64.23 | 7.5 | 52.75 | Apr 25, 2026 |
Selected entries from UGI’s top 10, sorted by UGI score. Ranks 4, 5 and 8 are another community fine-tune, the same GLM build without thinking, and a second Gemma 4 Heretic build.
Two patterns stand out in the raw data file. First, maximum willingness belongs entirely to the community: 66 of the 1,329 entries score 9.5 or higher on W/10, and not one is an official lab release. The highest official score is 8.2, for a small Mistral reasoning model. Second, de-restriction costs little general knowledge on UGI’s scale. Google’s original Gemma 4 31B scores 1.2 on W/10 and 38.91 on NatInt; the Heretic build above scores 10.0 and 36.53. For how those builds are made, see what abliteration is, and for the builds themselves, our best abliterated model map.
Which leaderboards track this, and what do they measure?
Two public leaderboards track censorship across many models today: UGI, which measures willingness on sensitive information, and SpeechMap.AI, which measures how completely models answer contentious political and social speech requests.
| UGI leaderboard | SpeechMap.AI | |
|---|---|---|
| Run by | One volunteer (DontPlanToEnd), Hugging Face Space | Public research project that takes donations |
| What it asks | Sensitive info, hazardous topics, adult entertainment knowledge, socio-political topics | Political argument, satire, religion, history, rights advocacy |
| Headline metric | UGI score, W/10 willingness, NatInt knowledge | % of requests answered completely; lab Free Speech Index |
| Questions | Private, to stop models training on the test | 2,120 prompts per model |
| Coverage | 1,329 entries, including community fine-tunes and abliterated builds | 415 lab model releases; we found no community uncensored builds in its list |
| Grading | Fixed questions, deterministic settings, per the maintainer | An LLM judge (Grok 4.1 Fast since March 2026) labels each answer complete, evasive or denial |
| Last update | Oct 17, 2026 | Oct 14, 2026 (lab table) |
SpeechMap’s lab ranking is a time-weighted average over each lab’s releases in its latest six-month window. As of October 14, 2026:
- Google DeepMind, 86.8
- xAI, 81.7
- Anthropic, 71.9
- Zhipu AI, 64.8
- Meituan, 63.6
OpenAI sits 10th at 57.1 and Mistral AI 12th at 56.2, though Mistral’s best model in the window peaks at 87.9. By single model, xAI’s Grok 4.5 is the highest release since April 2026 at 93.1%; Grok 4.20 in reasoning mode reached 98.2% in March. The academic benchmarks that measure over-refusal on harmless prompts, such as OR-Bench and XSTest, are covered in our guide to the LLM refusal benchmark landscape; they publish papers, not live rankings.
Where do the leaderboards agree and disagree?
They agree that xAI’s models refuse less than OpenAI’s, and they disagree sharply about Google and Anthropic.
| Model | UGI W/10 | UGI NatInt | SpeechMap % complete |
|---|---|---|---|
| Grok 4.5 | 5.8 | 60.21 | 93.1 |
| Mistral Medium 3.5 (no reasoning) | 6.0 | 40.39 | 87.9 |
| Gemini 4 Argon | 1.2–1.8 | 80.56–81.36 | 87.0 |
| Gemma 4 31B (official) | 1.2 | 38.91 | 84.8 |
| Claude Opus 5.5 | 2.8–4.2 | 69.26–73.28 | 82.8 |
| GPT-6.1 Sol | 3.2–3.8 | 71.13–78.26 | 69.5 |
| Grok 4.7 | 3.8 | 58.70 | 64.1 |
Ranges on UGI cover the reasoning or effort settings it tested. SpeechMap tests one default configuration per listed model.
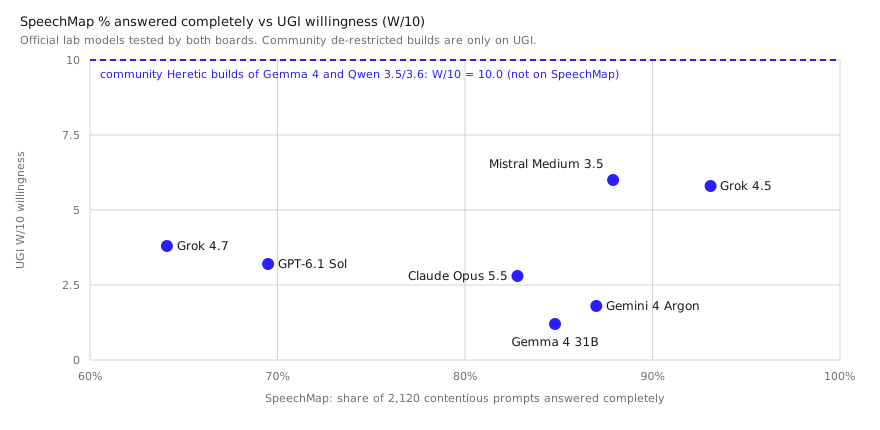
The split makes sense once you read what each one asks. SpeechMap asks a model to argue a position, write satire or defend a contested view. Google’s recent models do that readily. UGI pushes on sensitive information and on whether the model keeps following instructions under pressure, and Gemini 4 Argon gives way early. UGI’s own notes describe the same gap from the other side: a model can know a lot about a sensitive topic but treat it as educational and “refuse to form the information into something against its values.”
So “least censored” has no single answer. For political and social writing, SpeechMap is the better guide. For blunt factual questions on sensitive subjects and strict instruction following, UGI is. Only UGI covers community open-weight builds, which is where the 10/10 scores are. Our broader best uncensored AI ranking weighs both alongside privacy and price.
Why do scores move?
Scores move because the model, its settings and the grader all change, sometimes without the model name changing at all.
- Versions. Grok fell from 7.5 W/10 for Grok 4.20 in reasoning mode (April 2026) to 3.8 for Grok 4.7 (October 2026). On SpeechMap, Grok 4.7 completes 64.1%, against 93.1% for Grok 4.5, released in July.
- Reasoning mode. SpeechMap found Grok 4.20 completed 98.2% of requests with reasoning and 62.6% without. Mistral Medium 3.5 goes the other way: 87.9% without reasoning, 70.5% with it.
- Effort and prompt template. UGI lists each setting as its own row. Claude Opus 5.5 ranges from 2.8 to 4.2 W/10 across five effort levels, and open models are tested with or without a thinking prefill, which changes their scores.
- The judge. In March 2026 SpeechMap moved its grader from GPT-4o to Grok 4.1 Fast, mainly to cut judging costs by 93%. About 5% of its 569,000 past judgments changed, mostly between complete and evasive, and several Anthropic models lost points. The maintainer notes that “any two models will disagree on a substantial fraction of all judgements.”
- Coverage gaps. A model missing from a board is untested, not uncensored. UGI’s maintainer said in March 2026 that testing had cost $1,500 in two months and that he would test fewer fine-tunes and merges, focusing on API models, base models and highly requested builds (discussion #624).
The open source LLM leaderboard guide covers the same freshness problem for capability boards.
What do developers report in practice?
Developers mostly treat UGI as the reference for uncensored models, with the caveat that a high score does not guarantee zero refusals in your own use.
- It is the default citation. A Hacker News commenter in July 2026 called UGI “a very good and well maintained leaderboard”. They noted that stock Chinese models refuse less than US ones, and that many of the top 10 are uncensored builds of open-weight models (HN). In February 2026, when Grok was in the news, another HN commenter cited UGI, where Grok was then first, as evidence that it is “relatively uncensored” compared with rivals (HN).
- Builders use it as their quality check. When the maintainer scaled back testing, one model author replied that UGI had been the only source telling them which of their releases were good, since KL divergence “just acts as a small pointer” (HF discussion #624).
- Small samples blur close scores. In December 2024 a user worked out that W/10 then rested on about 11 questions, so a 9.1 and a 10 were hard to tell apart. Another said some W/10 ratings didn’t match their own testing (HF discussion #71). The test set has grown since, but treat small gaps as ties.
- Top scores still refused for some. One r/LocalLLaMA user wrote in December 2024 that they tested several models from the top of UGI, still hit refusals, and built their own test across 65 uncensored and abliterated models (Reddit).
The practical reading: use the boards to shortlist, then check refusals on your own prompts.
FAQ
What is the UGI leaderboard?
UGI (Uncensored General Intelligence) is a volunteer-run Hugging Face Space that scores LLMs on knowledge of sensitive topics, willingness to answer (W/10) and general intelligence (NatInt). Its questions are private so models can’t be trained on them. It listed 1,329 model entries as of October 2026.
What is the least censored LLM?
On UGI willingness, community Heretic builds of Gemma 4 31B and Qwen 3.5 and 3.6 score the maximum 10.0. Among official models, xAI’s Grok 4.20 leads UGI overall. On SpeechMap’s political-speech test, Grok 4.20 in reasoning mode answered 98.2% in March 2026, and Grok 4.5 is the highest release since April at 93.1%.
Is there an uncensored LLM benchmark for local models?
UGI is the only live leaderboard that tests community fine-tunes and abliterated open-weight builds alongside API models. SpeechMap covers official lab releases only.
Why does Gemini rank high on SpeechMap but low on UGI?
They test different things. SpeechMap checks whether a model will argue contested political and social positions, which Gemini 4 Argon does 87.0% of the time. UGI pushes on sensitive information and instruction adherence, where Gemini 4 Argon scores 1.2 to 1.8 out of 10.
Does Refusal Rate publish its own uncensored LLM leaderboard?
Not yet. Every score on this page comes from UGI or SpeechMap as published on the dates shown.
Sources (8)
- UGI Leaderboard (Uncensored General Intelligence), DontPlanToEnd, Hugging Face Space, data updated Oct 17, 2026, fetched Nov 10, 2026
- UGI Leaderboard raw data file, ugi-leaderboard-data.csv, fetched Nov 10, 2026
- SpeechMap.AI lab leaderboard, updated Oct 14, 2026
- SpeechMap.AI model results (415 releases, 2,120 prompts), fetched Nov 10, 2026
- SpeechMap update: xAI loses top spot on lab leaderboard to Mistral AI, judge model changes (Mar 28, 2026)
- UGI Leaderboard discussion #624: I will be testing fewer finetunes/merges (Mar 23, 2026)
- UGI Leaderboard discussion #71: Next leaderboard update plans (Dec 2024)
- Hacker News comment on the UGI leaderboard and open-weight models (Jul 29, 2026)