The best uncensored AI in 2026, text only: local models, Venice, Candor, Featherless, OpenRouter, Le Chat and Grok, ranked on refusal data and privacy.
The best uncensored AI in 2026 is an open-weight model with its refusals removed, run on your own machine through Ollama or LM Studio: nothing leaves the device and no provider policy sits on top. For a hosted option, Venice is the most established uncensored chat app, with on-device history and a free tier. On the UGI leaderboard, Grok and Mistral answer more than GPT, Gemini or Claude, but none match a de-restricted open model.
- Nov 9, 2026
- 8, text only
- Local open model
- Venice
Key takeaways
- Local is the least restricted tier: a community de-restricted Gemma 4 31B scores 10.0 out of 10 on UGI's willingness metric, against 2.5 for Google's original.
- Venice is the most established hosted pick: free tier of 10 text prompts a day, Pro at $18 a month, chat history stored on your device.
- Benchmarks disagree on what 'uncensored' means. Google leads SpeechMap's contentious-speech index, while Gemini 3.6 Flash scores 2.2 out of 10 on UGI willingness.
- Grok depends on the version and mode: Grok 4.20 in reasoning mode scored 98.2% on SpeechMap but 62.6% without reasoning, and the newer Grok 4.7 scores 3.8 on UGI willingness.
- No service on this list allows illegal use. 'Uncensored' means fewer refusals on legal requests, not a legal exemption.
What is the best uncensored AI right now?
The best uncensored AI is a de-restricted open-weight model you run yourself; the best hosted one is Venice. That ranking comes from two public benchmarks and each service’s own pricing and privacy pages, all fetched on November 9, 2026. We have not run our own tests, so every score below is someone else’s measurement, cited.
| # | Option | Type | What it runs | Free tier | Paid from | Where your chats go |
|---|---|---|---|---|---|---|
| 1 | Ollama + an uncensored open model | Local runtime | Any open model you download, including abliterated and Heretic builds | Free for local use | $20/mo (cloud models only) | Your machine, for local models |
| 2 | LM Studio + an uncensored open model | Local desktop app | Same, via llama.cpp and MLX | Free | $20/mo (Bionic+ cloud) | “Nothing you enter… leaves your device” |
| 3 | Venice | Hosted chat app | Venice Uncensored 1.2, DeepSeek V4.1 Flash Uncensored (app default) and others | 10 text prompts/day | $18/mo (Pro) | History on your device; provider retention “trust-based” in Private mode |
| 4 | Candor (we build it) | Hosted web app | Open models with refusal removed from the weights | Free credits, no card | $19.99/mo | Kept up to 30 days for review unless you opt out |
| 5 | Featherless Chat | Hosted chat | Its open-model catalogue | None listed | $25/mo | “no logs” on the Chat plan |
| 6 | OpenRouter | Model router | Dolphin Mistral 24B Venice Edition, Hermes 4 405B and hundreds more | Pay per token | $0.20 in / $0.90 out per 1M (Dolphin) | Depends on the provider you route to |
| 7 | Le Chat (Mistral) | Mainstream assistant | Mistral models | Yes | $14.99/mo (Pro) | Training is opt-out |
| 8 | Grok (xAI) | Mainstream assistant | Grok 4.x | See grok.com | API $2 in / $6 out per 1M via OpenRouter | xAI’s terms |
Prices and privacy wording are quoted from each provider’s page on the fetch date. They change often, so check the linked page before you pay.
How did we pick and rank them?
We ranked by three things, in order: how often the model behind the service refuses legal requests, what happens to your prompts, and what it costs to start. The refusal side relies on two public benchmarks that measure different things:
- UGI leaderboard (Uncensored General Intelligence), a volunteer-run Hugging Face Space. Its W/10 score measures “how far a model can be pushed before it refuses to answer or deviates from instructions”, on a 0–10 scale. Its NatInt score measures general knowledge, which matters because a model that never refuses but knows nothing is not useful.
- SpeechMap.AI, which scores how often models fully answer requests on contentious political and social speech, and ranks labs by a six-month average.
Both are third-party measurements with their own judges and prompt sets. Neither is ours. For how refusal benchmarks are built and where they mislead, see our guide to LLM refusal rate benchmarks.
Scope: text AI only. Image generators, NSFW sites and AI companion or roleplay apps are left out on purpose. They solve a different problem, and most of the “uncensored AI” listicles ranking above this page mix them in, so you can’t tell whether a pick is good at answering a hard question or at something else.
Disclosure: Refusal Rate and Candor are built by the same team. Candor is listed fourth, below the options we think are stronger for most readers.
Is running a model locally the most uncensored option?
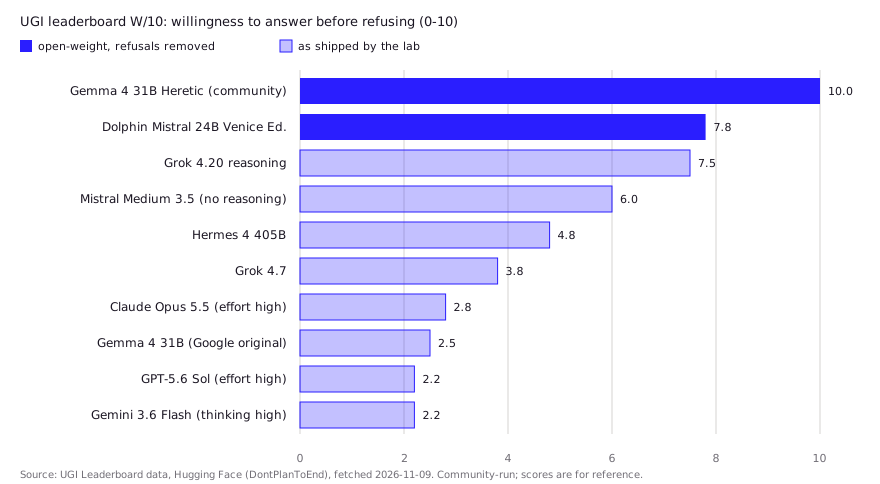
Yes: a local open model is the least restricted option, because nobody’s usage policy sits between you and the weights, and your prompts never leave the machine. On the UGI data, Google’s original Gemma 4 31B scores 2.5 out of 10 on willingness. A community “Heretic” build of the same model scores 10.0, with general knowledge (NatInt) roughly unchanged at about 36 against about 34–39 for the original, depending on settings.
1. Ollama. Ollama’s pricing page lists local use at $0 (“Run models locally… No subscription”); its paid plans cover its cloud models, which do leave your machine. You pull any open model, including abliterated or Heretic builds, and run it from the command line or a local API. Our guide to running an uncensored LLM locally covers hardware and setup.
2. LM Studio. LM Studio is the desktop app for people who’d rather not use a terminal. Its docs say it “can operate entirely offline” once you have model files, and that “nothing you enter into LM Studio when chatting with LLMs leaves your device.” The Free plan runs local models through llama.cpp and MLX. Its newer Bionic cloud models are optional and hosted in the US, so keep track of which one you’re talking to.
The catch is quality, not access. “Uncensored” builds vary a lot, and the label alone tells you nothing. The difference between abliterated, fine-tuned and merely prompted models is explained in abliterated vs uncensored vs fine-tuned.
Which hosted uncensored AI services are worth using?
Venice is the strongest hosted option on published data, followed by Candor (disclosed above), Featherless and OpenRouter, which suit different budgets and levels of control.
3. Venice. Venice is a chat app built around open and uncensored models. Its model list labels Venice Uncensored 1.2 and a DeepSeek V4.1 Flash Uncensored model (the app default) as uncensored, among others. The UGI leaderboard tested Dolphin Mistral 24B Venice Edition, the Apache-2.0 model Dolphin built with Venice on Mistral Small 24B, at 7.8 out of 10 on willingness, though with a modest 24.4 on general knowledge. The free tier gives 10 text prompts a day; Pro costs $18 a month. On privacy, Venice says “your conversation history stays on your device” and its proxy relays requests “without being stored”. It also says that in the default Private mode, the no-storage promise from model providers is enforced by contract, which the page itself calls “trust-based”; Pro adds TEE and end-to-end encrypted modes. Its terms still ban any illegal use. For the API side, see our Venice API review.
4. Candor (we build it). Candor is a browser-based chat app, installable to a phone’s home screen, that runs open models whose refusal behavior was removed from the weights. New accounts get free credits with no card; Monthly is $19.99 for 8,500 credits. Its FAQ says it blocks sexual content involving minors, help planning violence against real people and other illegal requests, and that users must be 18 or older. On data, the FAQ says Candor keeps a copy of conversations “for up to 30 days” for review unless you switch off “Help improve the app,” and that account deletion is permanent. It also generates images and video, which is outside this page’s scope. Its developer API was paused on the date we checked. No third-party benchmark has scored Candor’s models yet, so we can’t put a number next to it.
5. Featherless Chat. Featherless is a host for a large catalogue of open models, many of them community fine-tunes. The Chat plan costs $25 a month with up to 32K context and is described as “private, secure, and anonymous usage (no logs).” It suits people who want to try many uncensored fine-tunes without downloading them.
6. OpenRouter. OpenRouter is a router, not a model. It lists Dolphin Mistral 24B Venice Edition at $0.20 in and $0.90 out per 1M tokens and Hermes 4 405B at $1 / $3. Privacy depends on the provider each request lands on: you can tell OpenRouter not to route to providers that train on data, and filter for zero-retention providers. The API-only comparison lives in our uncensored AI API comparison.
Are mainstream assistants like Grok or Le Chat uncensored?
No mainstream assistant is uncensored, but Mistral’s and xAI’s models refuse less than OpenAI’s, Google’s or Anthropic’s on the UGI willingness metric.
7. Le Chat (Mistral). Mistral Medium 3.5 scores 4.8–6.0 out of 10 on UGI willingness depending on reasoning, against 2.2 for GPT-5.6 Sol and 2.8 for Claude Opus 5.5 at high effort. SpeechMap’s lab table shows Mistral’s best recent model at 87.9% complete answers. Le Chat has a free tier, Pro at $14.99 a month, and model training listed as opt-out. Mistral’s usage policy, effective June 11, 2026, still bans hate, fraud and CSAM outright.
8. Grok (xAI). Grok’s reputation as the uncensored mainstream bot depends on which version you get. SpeechMap reported in March 2026 that Grok 4.20 completed 98.2% of requests in reasoning mode but 62.6% without it. On UGI, Grok 4.20 reasoning scores 7.5 on willingness, while the newer Grok 4.7, tested October 2, 2026, scores 3.8. On SpeechMap’s October 14 lab table, xAI ranks second at 81.7, behind Google DeepMind.
That last point shows why one benchmark isn’t enough. Google tops SpeechMap’s contentious-speech index at 86.8, yet Gemini 3.6 Flash scores 2.2 on UGI willingness, which focuses on sensitive information and instruction following. “Least censored” depends on what you ask.
What do users report in practice?
Community reports mostly agree with the benchmarks: uncensored open models answer more, but quality and safety vary widely. These are reports from other people, not our tests:
- Grok can refuse what others allow. A Hacker News commenter wrote on November 8, 2026 that Grok refused religion- and nationality-based roleplay that ChatGPT and Claude went along with (HN). Another said in January that DeepSeek is “probably less censored than grok” and that the Dolphin family gave them the best results (HN).
- Most uncensored builds are weak. One developer pointed out that there are tens of thousands of “uncensored”, “abliterated” or “heretic” models on Hugging Face and Ollama, and warned that most “aren’t very good, essentially lobotomized, and totally broken if you enable thinking” (HN).
- Hosted apps can keep hidden instructions. A Venice user filed a feedback post titled “Removing the system prompt does not completely remove venice.ai’s system prompt” (Venice feedback board).
- Removing refusals doesn’t remove training bias. An April 2026 analysis on Morgin found that abliteration slightly increased a base model’s word-avoidance score, from 243.8 to 258.1, so models sold as uncensored still carry the filtering of their training data (Morgin).
- Edited weights can hide a backdoor. ProjectDiscovery showed in October 2026 that a poisoned fine-tune can pass evals and then exfiltrate
.envcredentials through a coding agent when a trigger appears. Download edited models only from publishers you trust, and sandbox agents that use them (ProjectDiscovery; HN discussion).
What does “uncensored” not mean?
“Uncensored” means a model refuses fewer legal requests. It does not mean the service allows illegal use, and it does not mean the model is accurate.
- Terms still apply. Venice’s terms ban using the service “for any illegal purpose,” Mistral’s policy bans fraud and CSAM, and Candor blocks illegal requests. Open-weight model licences carry their own acceptable-use terms, whether or not refusals were removed.
- Fewer refusals isn’t more knowledge. Several of the most willing models on UGI score far lower on general knowledge than frontier models. Willingness and competence are separate axes, so check both.
- Privacy claims are claims. Unless the model runs on your own hardware, “no logs” and “private” depend on contracts and trust. Read the provider’s own page and decide what you’re willing to send.
FAQ
What is the most unrestricted AI?
An open-weight model with its refusals removed, run locally through Ollama or LM Studio. On the UGI leaderboard, community Heretic builds of Gemma 4 31B reach the maximum 10 out of 10 on willingness, and no provider policy applies because nothing leaves your machine.
Is there a free uncensored AI?
Yes. Ollama and LM Studio are free for local use if your hardware can run the model. Among hosted options, Venice’s free tier allows 10 text prompts a day, and Candor (which we build) gives new accounts free credits with no card.
Which AI chatbot has the least censorship?
Among mainstream assistants, Mistral and xAI models score highest on UGI willingness, though Grok varies a lot by version and mode. Dedicated uncensored apps like Venice, and open models you run yourself, refuse less than any mainstream assistant.
Is using uncensored AI legal?
Using a model that answers legal questions without refusing is legal. What you ask it and what you do with the output are still covered by the law and by the service’s terms, which on every service here ban illegal use.
Sources (10)
- UGI Leaderboard (Uncensored General Intelligence), DontPlanToEnd, Hugging Face Space, data updated Oct 17, 2026
- SpeechMap.AI lab leaderboard, updated Oct 14, 2026
- SpeechMap update: xAI loses top spot on lab leaderboard to Mistral AI, judge model changes (Mar 28, 2026)
- Venice pricing
- Venice privacy
- Candor homepage, pricing and FAQ
- Offline Operation, LM Studio docs
- Featherless plans, Featherless docs
- Provider logging and data policies, OpenRouter docs
- How abliterated models can get you pwned, ProjectDiscovery (Oct 6, 2026)